Charts & InfographicsGPT Image 2InfographicVectorSlide thuyết trìnhBố cục đối xứngSơ đồ kỹ thuật
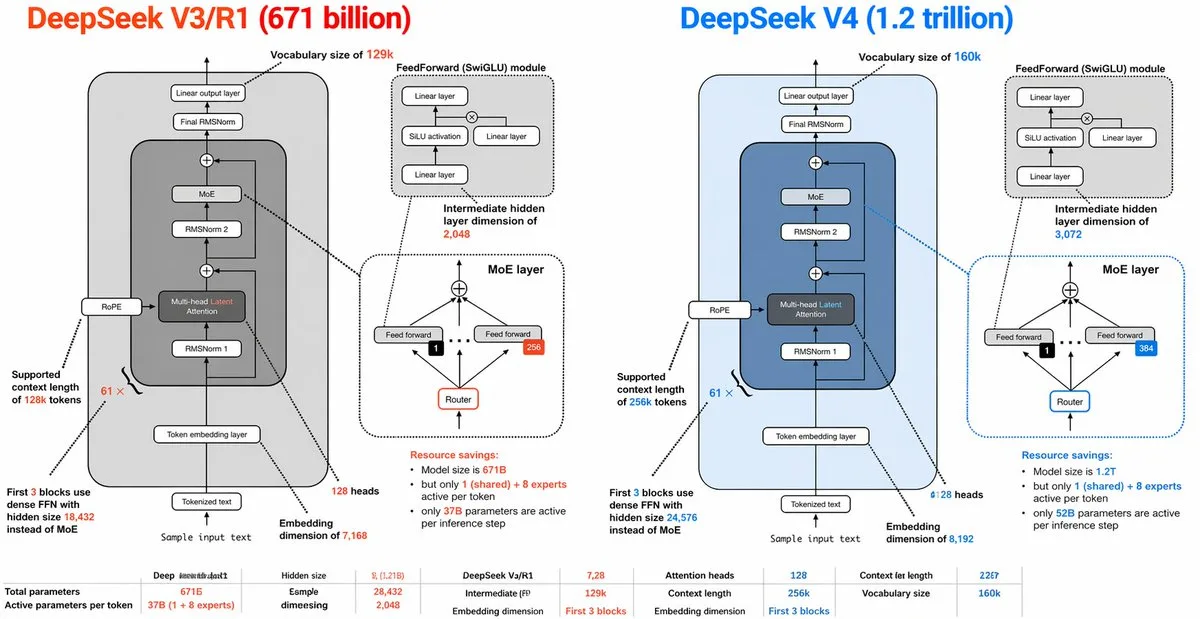
Infographic so sánh kiến trúc DeepSeek V3 và V4
Prompt dạng cấu trúc JSON chi tiết để tạo infographic so sánh kiến trúc hai mô hình AI DeepSeek V3/R1 và DeepSeek V4 đặt cạnh nhau. Hình ảnh thể hiện sơ đồ kỹ thuật dạng slide thuyết trình với các khối chức năng, mô-đun MoE, SwiGLU và bảng thông số so sánh.
Bản tiếng Anh
{"type":"side-by-side AI architecture comparison infographic","style":"clean technical diagram, white background, thin black outlines, rounded rectangles, dashed callout boxes, color-coded highlights, presentation-slide aesthetic, vector infographic","canvas":{"aspect_ratio":"2:1","resolution":"wide horizontal"},"title_row":{"left_title":"DeepSeek V3/R1 (671 billion)","right_title":"DeepSeek V4 (1.2 trillion)","left_title_color":"bright orange-red","right_title_color":"bright blue"},"layout":{"columns":2,"sections":[{"title":"DeepSeek V3/R1 (671 billion)","position":"left half","count":9,"labels":["Vocabulary size of 129k","FeedForward (SwiGLU) module","Intermediate hidden layer dimension of 2,048","MoE layer","Supported context length of 128k tokens","First 3 blocks use dense FFN with hidden size 18,432 instead of MoE","Sample input text","Embedding dimension of 7,168","128 heads"]},{"title":"DeepSeek V4 (1.2 trillion)","position":"right half","count":9,"labels":["Vocabulary size of 160k","FeedForward (SwiGLU) module","Intermediate hidden layer dimension of 3,072","MoE layer","Supported context length of 256k tokens","First 3 blocks use dense FFN with hidden size 24,576 instead of MoE","Sample input text","Embedding dimension of 8,192","128 heads"]},{"title":"bottom comparison table","position":"bottom full width","count":10,"labels":["Total parameters","Active parameters per token","Hidden size","Esmple dimesiegn","DeepSeek V3/R1","Intermediate (FF)","Attention heads","Context length","Embedding dimension","Vocabulary size"]}]},"left_panel":{"background":"very light gray rounded rectangle","main_stack":{"count":8,"blocks":["Tokenized text","Token embedding layer","RMSNorm 1","Multi-head Latent Attention","RMSNorm 2","MoE","Final RMSNorm","Linear output layer"]},"side_module":"RoPE attached to the attention block on the left side","attention_block":{"label":"Multi-head Latent Attention","accent":"orange-red text for the word Latent"},"feedforward_inset":{"title":"FeedForward (SwiGLU) module","count":4,"blocks":["Linear layer","SiLU activation","Linear layer","Linear layer"],"diagram":"two branches multiplied, then projected"},"moe_inset":{"title":"MoE layer","count":5,"blocks":["top combine node","Feed forward","Feed forward","Router","expert count badge 256"],"details":"small black square with 1 selected expert, arrows routing upward to experts, dotted divider line"},"annotations":{"vocab":"Vocabulary size of 129k","ff_dim":"Intermediate hidden layer dimension of 2,048","context":"Supported context length of 128k tokens","dense_first_blocks":"First 3 blocks use dense FFN with hidden size 18,432 instead of MoE","resource_savings":"Resource savings: Model size is 671B but only 1 (shared) + 8 experts active per token; only 37B parameters are active per inference step"},"bottom_stats":{"count":10,"items":["Total parameters: 671B","Active parameters per token: 37B (1 + 8 experts)","Hidden size: 7,128","Esmple dimesiegn: 28,432","Intermediate (FF): 2,048","Attention heads: 128","Context length: 128k","Embedding dimension: First 3 blocks","Context ler length: 22G7","Vocabulary size: 129k"]}},"right_panel":{"background":"very light blue rounded rectangle","main_stack":{"count":8,"blocks":["Tokenized text","Token embedding layer","RMSNorm 1","Multi-head Latent Attention","RMSNorm 2","MoE","Final RMSNorm","Linear output layer"]},"side_module":"RoPE attached to the attention block on the left side","attention_block":{"label":"Multi-head Latent Attention","accent":"blue text for the word Latent"},"feedforward_inset":{"title":"FeedForward (SwiGLU) module","count":4,"blocks":["Linear layer","SiLU activation","Linear layer","Linear layer"],"diagram":"same structure as left panel"},"moe_inset":{"title":"MoE layer","count":5,"blocks":["top combine node","Feed forward","Feed forward","Router","expert count badge 384"],"details":"small black square with 1 selected expert, arrows routing upward to experts, dotted divider line, blue border emphasis"},"annotations":{"vocab":"Vocabulary size of 160k","ff_dim":"Intermediate hidden layer dimension of 3,072","context":"Supported context length of 256k tokens","dense_first_blocks":"First 3 blocks use dense FFN with hidden size 24,576 instead of MoE","resource_savings":"Resource savings: Model size is 1.2T but only 1 (shared) + 8 experts active per token; only 52B parameters are active per inference step"},"bottom_stats":{"count":10,"items":["Total parameters: 1.2T","Active parameters per token: 52B (1 + 8 experts)","Hidden size: 7,2B","Esmple dimesiegn: 28,432","Intermediate (FF): 3,072","Attention heads: 128","Context length: 256k","Embedding dimension: First 3 blocks","Context ler length: 22G7","Vocabulary size: 160k"]}},"global_notes":"Create a highly detailed transformer architecture comparison diagram with mirrored layouts. Each half contains one large model stack diagram plus 2 inset diagrams: 1 feedforward module and 1 MoE layer. Use arrows between blocks, tiny technical labels, and connector lines from labels to the relevant components. Keep the typography dense and slide-like, with orange-red used for all V3/R1 emphasis and blue used for all V4 emphasis. Include a small bottom row of compact tabular metrics spanning the width. Preserve the slightly imperfect, human-made infographic look with very small text and crowded annotations."}Bản tiếng Việt
{"type":"infographic so sánh kiến trúc AI đặt cạnh nhau","style":"sơ đồ kỹ thuật gọn gàng, nền trắng, viền đen mỏng, hình chữ nhật bo góc, hộp chú thích nét đứt, các điểm nổi bật mã hóa theo màu sắc, tính thẩm mỹ dạng slide thuyết trình, infographic vector","canvas":{"aspect_ratio":"2:1","resolution":"wide horizontal"},"title_row":{"left_title":"DeepSeek V3/R1 (671 tỷ)","right_title":"DeepSeek V4 (1,2 nghìn tỷ)","left_title_color":"đỏ cam sáng","right_title_color":"xanh dương sáng"},"layout":{"columns":2,"sections":[{"title":"DeepSeek V3/R1 (671 tỷ)","position":"nửa bên trái","count":9,"labels":["Kích thước từ vựng 129k","Mô-đun FeedForward (SwiGLU)","Kích thước lớp ẩn trung gian 2.048","Lớp MoE","Độ dài ngữ cảnh được hỗ trợ 128k token","3 khối đầu tiên sử dụng FFN dày đặc với kích thước ẩn 18.432 thay vì MoE","Văn bản đầu vào mẫu","Kích thước embedding 7.168","128 head"]},{"title":"DeepSeek V4 (1,2 nghìn tỷ)","position":"nửa bên phải","count":9,"labels":["Kích thước từ vựng 160k","Mô-đun FeedForward (SwiGLU)","Kích thước lớp ẩn trung gian 3.072","Lớp MoE","Độ dài ngữ cảnh được hỗ trợ 256k token","3 khối đầu tiên sử dụng FFN dày đặc với kích thước ẩn 24.576 thay vì MoE","Văn bản đầu vào mẫu","Kích thước embedding 8.192","128 head"]},{"title":"bảng so sánh phía dưới","position":"toàn bộ chiều rộng phía dưới","count":10,"labels":["Tổng số tham số","Tham số hoạt động mỗi token","Kích thước ẩn","Esmple dimesiegn","DeepSeek V3/R1","Lớp trung gian (FF)","Số đầu attention","Độ dài ngữ cảnh","Kích thước embedding","Kích thước từ vựng"]}]},"left_panel":{"background":"hình chữ nhật bo góc màu xám rất nhạt","main_stack":{"count":8,"blocks":["Văn bản đã tokenize","Lớp token embedding","RMSNorm 1","Multi-head Latent Attention","RMSNorm 2","MoE","RMSNorm cuối cùng","Lớp đầu ra tuyến tính"]},"side_module":"RoPE gắn vào khối attention ở phía bên trái","attention_block":{"label":"Multi-head Latent Attention","accent":"orange-red text for the word Latent"},"feedforward_inset":{"title":"Mô-đun FeedForward (SwiGLU)","count":4,"blocks":["Linear layer","SiLU activation","Linear layer","Linear layer"],"diagram":"hai nhánh nhân với nhau, sau đó được chiếu (projected)"},"moe_inset":{"title":"Lớp MoE","count":5,"blocks":["top combine node","Feed forward","Feed forward","Router","expert count badge 256"],"details":"ô vuông nhỏ màu đen với 1 chuyên gia được chọn, các mũi tên định tuyến hướng lên các chuyên gia, đường phân cách nét đứt"},"annotations":{"vocab":"Kích thước từ vựng 129k","ff_dim":"Kích thước lớp ẩn trung gian 2.048","context":"Độ dài ngữ cảnh được hỗ trợ 128k token","dense_first_blocks":"3 khối đầu tiên sử dụng FFN dày đặc với kích thước ẩn 18.432 thay vì MoE","resource_savings":"Tiết kiệm tài nguyên: Kích thước mô hình là 671B nhưng chỉ có 1 (chia sẻ) + 8 chuyên gia hoạt động trên mỗi token; chỉ có 37B tham số hoạt động trong mỗi bước suy luận"},"bottom_stats":{"count":10,"items":["Tổng số tham số: 671B","Tham số kích hoạt trên mỗi token: 37B (1 + 8 chuyên gia)","Kích thước ẩn: 7,128","Esmple dimesiegn: 28,432","Lớp trung gian (FF): 2,048","Số đầu attention: 128","Độ dài ngữ cảnh: 128k","Kích thước embedding: 3 khối đầu tiên","Context ler length: 22G7","Kích thước từ vựng: 129k"]}},"right_panel":{"background":"hình chữ nhật bo góc màu xanh dương rất nhạt","main_stack":{"count":8,"blocks":["Văn bản đã tokenize","Lớp token embedding","RMSNorm 1","Multi-head Latent Attention","RMSNorm 2","MoE","RMSNorm cuối cùng","Lớp đầu ra tuyến tính"]},"side_module":"RoPE gắn vào khối attention ở phía bên trái","attention_block":{"label":"Multi-head Latent Attention","accent":"blue text for the word Latent"},"feedforward_inset":{"title":"Mô-đun FeedForward (SwiGLU)","count":4,"blocks":["Linear layer","SiLU activation","Linear layer","Linear layer"],"diagram":"cấu trúc tương tự như bảng bên trái"},"moe_inset":{"title":"Lớp MoE","count":5,"blocks":["top combine node","Feed forward","Feed forward","Router","expert count badge 384"],"details":"ô vuông nhỏ màu đen với 1 chuyên gia được chọn, các mũi tên định tuyến hướng lên các chuyên gia, đường phân cách nét đứt, viền xanh dương nhấn mạnh"},"annotations":{"vocab":"Kích thước từ vựng 160k","ff_dim":"Kích thước lớp ẩn trung gian 3.072","context":"Độ dài ngữ cảnh được hỗ trợ 256k token","dense_first_blocks":"3 khối đầu tiên sử dụng FFN dày đặc với kích thước ẩn 24.576 thay vì MoE","resource_savings":"Tiết kiệm tài nguyên: Kích thước mô hình là 1.2T nhưng chỉ có 1 (chia sẻ) + 8 chuyên gia hoạt động trên mỗi token; chỉ có 52B tham số hoạt động trong mỗi bước suy luận"},"bottom_stats":{"count":10,"items":["Tổng số tham số: 1.2T","Tham số kích hoạt trên mỗi token: 52B (1 + 8 chuyên gia)","Kích thước ẩn: 7,2B","Esmple dimesiegn: 28,432","Lớp trung gian (FF): 3.072","Số đầu attention: 128","Độ dài ngữ cảnh: 256k","Kích thước embedding: 3 khối đầu tiên","Context ler length: 22G7","Kích thước từ vựng: 160k"]}},"global_notes":"Tạo một sơ đồ so sánh kiến trúc transformer có độ chi tiết cao với bố cục đối xứng gương. Mỗi nửa chứa một sơ đồ xếp chồng mô hình lớn cùng với 2 sơ đồ lồng vào: 1 mô-đun feedforward và 1 lớp MoE. Sử dụng các mũi tên giữa các khối, các nhãn kỹ thuật nhỏ và các đường nối từ nhãn đến các thành phần liên quan. Giữ kiểu chữ dày đặc và mang phong cách slide thuyết trình, với màu đỏ cam được dùng cho tất cả các điểm nhấn mạnh V3/R1 và màu xanh dương dùng cho tất cả các điểm nhấn mạnh V4. Thêm một hàng dưới cùng nhỏ gồm các chỉ số dạng bảng gọn gàng trải dài toàn bộ chiều rộng. Giữ lại vẻ ngoài infographic do con người tạo ra hơi không hoàn hảo với văn bản rất nhỏ và các chú thích dày đặc."}Mẹo sử dụng
Giữ nguyên cấu trúc JSON để mô hình AI nhận diện chính xác các thành phần bố cục và nhãn kỹ thuật. Bạn có thể tùy chỉnh thông số các lớp, số lượng tham số hoặc màu sắc nhấn mạnh cho từng phiên bản mô hình.
Nguồn và quyền sử dụng
- Nguồn
- https://x.com/realsigridjin/status/2047562672871440385#reversed-0
- Tác giả gốc
- Sigrid Jin 🌈🙏
- License prompt
- CC-BY-4.0
- License ảnh
- CC-BY-4.0